
How do you optimize B2B content for ChatGPT and Perplexity?
You optimize for each engine separately, because they cite different pages. Across 15,000 long-tail queries, only 12% of the URLs AI assistants cited also ranked in Google's top 10, and the figure ranged from 28.6% for Perplexity down to 6.1% for ChatGPT's reference list. One page tuned to generic advice wins on one engine and misses the others.
That single number reorders the work. Most advice on this topic treats "AI search" as one destination with one set of rules, so it hands you a checklist: write direct answers, add schema, keep sections short, refresh often. Some of that helps. None of it tells you which engine you are actually losing, and without that, you're spending budget on a guess.
If you only take one thing from this page, take the Engine Coverage Gap Test. Twelve checks, no sign-up, scores itself in your browser.
What this guide covers:
- Why per-engine divergence makes "optimize for AI search" the wrong unit of work
- What the engine-by-engine data actually says, including the Bing inversion nobody quotes
- What carries over from your existing SEO, and the schema claim that does not survive Google's own documentation
- The Engine Coverage Gap Test: 12 checks you can run this week
- What happened when we ran our own citation check against a control, and why it changed how we measure
- What the tools can and cannot tell you, with today's prices and coverage
Key Takeaway
Being cited by ChatGPT and being cited by Perplexity are two different jobs with two different source pools. Until you measure them separately, any statement about your AI visibility is an average of things that don't average.
Why "optimize for AI search" is the wrong unit of work
AI assistants don't draw from a shared index of best pages. Ahrefs ran 15,000 long-tail queries through ChatGPT, Gemini, Copilot and Perplexity in early July 2025 and checked how many cited URLs also sat in the classic top 10. The average was 12%. The spread was the finding.
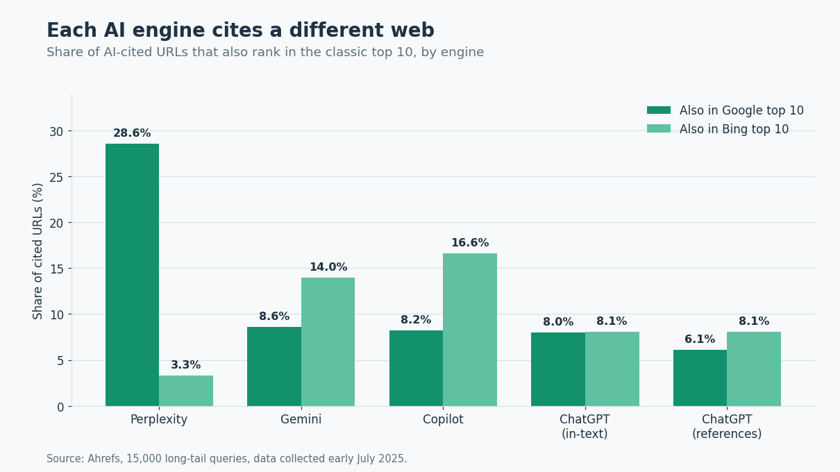
Perplexity sits at 28.6% against Google's top 10. ChatGPT sits at 8.0% for in-text citations and 6.1% for the links in its reference list. So a page that earns its way into Google's top 10 has a reasonable chance of being pulled into a Perplexity answer, and very little chance of being pulled into a ChatGPT one.
Then look at the Bing column, which almost nobody quotes. Perplexity's overlap with Bing's top 10 is 3.3%. Copilot's is 16.6%, double its 8.2% on Google. The two engines sit on opposite sides of the same comparison. If your only lever is classic ranking, you're pulling a lever that moves one engine and barely touches another.
| Assistant | Cited URLs also in Google top 10 | Cited URLs also in Bing top 10 | What that implies |
| Perplexity | 28.6% | 3.3% | Closest to classic Google ranking. Your SEO work shows up here first. |
| Copilot | 8.2% | 16.6% | Leans Bing. Worth its own check if your buyers sit in a Microsoft estate. |
| Gemini | 8.6% | 14.0% | Also leans Bing, despite the Google surname. |
| ChatGPT (in-text) | 8.0% | 8.1% | Roughly independent of both. Ranking buys you little here. |
| ChatGPT (references) | 6.1% | 8.1% | The lowest overlap in the set. |
Source: Ahrefs, only 12% of AI-cited URLs rank in Google's top 10. 15,000 long-tail queries, data collected early July 2025, measured with Brand Radar.
One caveat worth stating plainly, because peppereffect publishes the weaknesses alongside the numbers: this is a single vendor's dataset on long-tail queries at one point in time, and the engines have shipped changes since. Treat the ordering as reliable and the decimal places as approximate. The ordering is enough to change what you do.
Google AI Overviews moved away from the top 10
AI Overviews used to be the exception that made classic SEO look sufficient. In July 2025, Ahrefs examined 1.9 million citations from 1 million AI Overviews and found 76.1% of cited pages ranked in the top 10 for the same query. Optimize for Google, get the Overview.
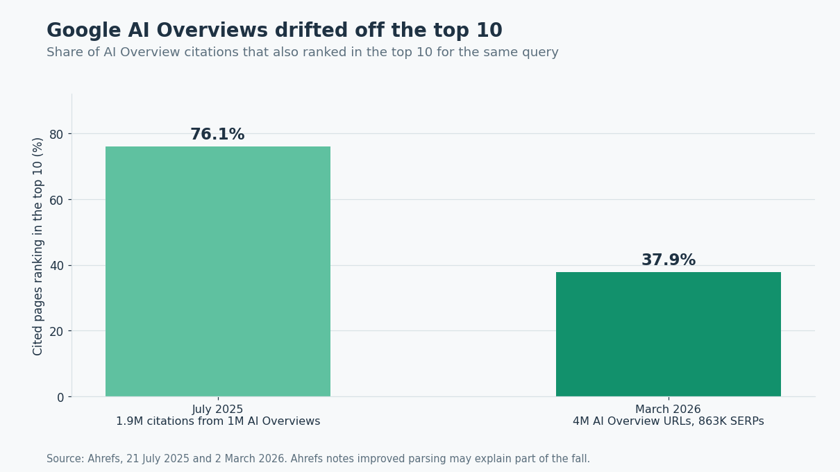
By March 2026, across 863,000 keyword SERPs and 4 million AI Overview URLs, that figure was 37.9%. Looking only at standard organic listings gave 37.1% in the top 10, 26.2% between 11 and 100, and 36.7% outside the top 100 entirely. Among the citations that ranked nowhere, 18.2% were YouTube URLs.
Ahrefs is careful about the cause, and so are we. Their own write-up notes that improved parsing since July 2025 may explain part of the fall, and points to Google's query fan-out process as a possible driver of the rest. This is a correlation across two differently-measured snapshots, not a proven mechanism. What it isn't is a reason to keep assuming AI Overviews are a free ride on your rankings.
Sources: Ahrefs, 2 March 2026; Ahrefs, 21 July 2025.
What carries over from your SEO, and what does not
Most of your existing work still pays. Crawlability, page speed, clear information architecture and genuine subject authority all feed the indexes these engines read. What changes is the unit of success. You're no longer competing for a position in a list. You're competing to be one of the few sources an answer names. Pew's browsing-data study found that 88% of Google AI summaries cited three or more sources, and only 1% cited a single source. A results page lists ten links. An answer names a handful.
| Practice | Still pays | What the evidence says |
| Technical crawlability and speed | Yes | Every engine has to fetch and parse the page before it can quote it. |
| Topical depth on one subject | Yes | Depth is what puts you in the candidate pool an engine draws from. |
| Classic top-10 ranking | Partly | 28.6% citation overlap on Perplexity, 6.1% on ChatGPT's reference list. |
| FAQ schema as a citation lever | No, for Google | Google's own documentation: "There's also no special schema.org structured data that you need to add." No engine has published the opposite. |
| Publishing volume | No | Few named sources per answer. Our reading: extra pages on one topic mostly compete with each other. |
Sources: Google Search Central, AI features documentation; Pew Research Center, 22 July 2025 (900 US adults, 68,879 searches).
The schema line deserves emphasis, because the opposite claim is everywhere, usually as a specific multiplier attached to FAQ markup. Google's published guidance on AI features says no special structured data is required. Be precise about the scope: that sentence covers Google's AI features and nothing else. OpenAI, Perplexity and Anthropic have published no equivalent statement either way, so the honest position on those engines is that nobody outside them knows. What no one has produced is a study with a stated method showing schema lifts citations. Keep your schema accurate and matched to visible text, which is worth doing for other reasons. Stop treating it as the lever that gets you cited.
The mistake we see most
Teams pick the tactic with the biggest published multiplier next to it. Almost every one of those multipliers traces back to a vendor blog with no stated method, and several contradict the platform's own documentation. Ask two questions of any number before you act on it: who measured it, and on what sample. If either answer is missing, the number is marketing.
The Engine Coverage Gap Test
Here's the diagnostic we run before touching a single page. Twelve checks in four layers. It tells you whether you're measuring AI visibility across the engines your buyers use, or measuring one engine and assuming the rest behave the same way. Work through it on paper, or use the interactive version, which scores itself in your browser and sends nothing anywhere.
| # | Check | Passing threshold |
| 1 | Buyer-intent prompts written the way your buyer speaks, not keywords | 10 or more on file |
| 2 | No prompt contains your brand name | Zero brand mentions |
| 3 | Category, comparison and problem prompt shapes all covered | 2 or more of each |
| 4 | Tested on ChatGPT, AI Overviews, Perplexity and Gemini | 4 engines minimum |
| 5 | Copilot tested, or ruled out in writing | Decision recorded |
| 6 | Cited URLs captured, never mention counts alone | URL for every answer |
| 7 | Results broken out per engine rather than blended into one index | Per-engine reporting |
| 8 | A positive control runs alongside every measurement | Control returns "cited" |
| 9 | Same prompt set re-run on a fixed cadence | 2 or more runs per quarter |
| 10 | Every lost prompt mapped to the page that should have won it | A named page per loss |
| 11 | Winning competitor and winning URL recorded per loss | Both captured |
| 12 | Fix list is content and authority work, not tool configuration | Majority of actions change pages |
Score it out of 12. Below 5, any claim you make about AI visibility is an opinion. Between 5 and 8, you're measuring one engine and extrapolating, which the overlap data says you cannot do. Between 9 and 11 you have real coverage with a known hole, usually check 8 or check 11. At 12 you have a measurement programme rather than a dashboard subscription.
Check 8 is the one almost nobody runs. It's also the one that caught us.
What we found when we tested our own measurement
In August 2026 our AEO citation check started returning zero for every domain we pointed it at. Zero is a plausible result for a small site, so it went unquestioned for a while. Then we ran a control, and the control also came back zero.
We repeated the test on 30 September 2026 for this article. Querying our own domain across five buyer-intent keywords returned a citation rate of 0. The tool's own diagnostics explained why: the response carried api_source: serp_ai_overview and the note "LLM Mentions probe returned no data. Using SERP AI Overview fallback." The probe that was supposed to read assistant answers returned nothing, so the check quietly measured Google's AI Overview instead and reported the result under the same label.
Then the control. We ran three of the same keywords against ahrefs.com, a domain with a large, heavily linked published footprint on exactly these topics, including the studies cited earlier in this article. Citation rate: 0. Identical fallback note. It scored the same as a site with almost none.
What that means
A check that returns the same answer for a heavily cited domain and a barely cited one has no discriminative power. That isn't bad measurement. No measurement is happening. The defensible statement from that run is "not present in the AI Overview citations for these five queries". The statement we could not have supported, and which the dashboard invited, is "invisible in ChatGPT and Perplexity".
The fix is cheap and it's now check 8 on our list: every measurement run includes a domain we already know is cited. If the control fails, the run is void and every zero in it gets thrown away. Without that control we would have briefed a client on a broken instrument and never known.
What the AI search optimization tools can and cannot tell you
Buyers ask us which tool to use more often than they ask what to publish. Fair question. The category splits into four kinds of product that do different jobs, and the cheap end of it is thin exactly where the overlap data says you need coverage.
| Type | What it does | What it cannot do |
| Visibility trackers | Run a prompt set across engines on a schedule and report mentions, share of voice and cited sources | Tell you why you lost, or write the page that wins it back |
| Content optimizers | Score a draft for structure, directness and source density | Know whether any engine actually cites the published result |
| SEO suites with AI modules | Add AI mention tracking to a toolset you already pay for | Match a dedicated tracker's prompt volume or engine breadth |
| Free graders | Give a one-off snapshot good enough to decide whether the gap is real | Track change over time, or probe the model your buyers actually use |
Two specifics, both read on 30 September 2026, that matter more than the feature lists. HubSpot's AI Search Grader is genuinely free and checks three engines, but it probes GPT-5.4 mini rather than the model most people search with, and it says outright that its recommendations are AI-generated and not reviewed by a human. Otterly.ai's Lite plan is $29 a month for 15 prompts and covers ChatGPT, Google AI Overviews, Perplexity and Copilot; Claude, Gemini and Google AI Mode are paid add-ons on every tier, including the $489 Premium plan.
Sources: HubSpot AI Search Grader, Otterly.ai pricing. Both read 30 September 2026; prices and engine coverage change often.
Read that against the overlap table. Gemini is one of the two engines that lean Bing rather than Google, which makes it one of the engines most likely to surprise you, and on the entry tier it's an extra line item. Engine coverage is the specification. Everything else on the comparison page is secondary.
Want the measurement run properly, with controls, before you spend on content? That's what our AI visibility measurement engagement is for.
What this page looked like before we rewrote it
It would be poor form to publish a piece on click-defensibility without showing our own numbers. Over the 90 days to 30 September 2026, the previous version of this page took 673 impressions and zero clicks in Google Search Console. Its strongest query, "how to optimize b2b content for chatgpt and perplexity", brought 269 impressions at an average position of 5.0. Position five. No clicks at all.
That isn't a ranking problem. Our reading is that a page at position five which nobody opens has already given away its answer in the snippet: the old version listed tactics anyone could summarize in three sentences, so the summary got read and the link did not. It also carried statistics we could not trace to a primary source, including a multiplier attached to FAQ schema that contradicts Google's own documentation.
One competing explanation is worth stating, because we cannot rule it out. A large share of these queries are long machine-phrased prompts rather than things a person types, so some of those impressions may come from automated query sets that were never going to produce a human click. That would inflate impressions and depress CTR regardless of how good the page is. Both explanations point the same way: publish something a summary cannot replace.
The query list held something else worth knowing. A large share of the impressions arrived as full natural-language prompts rather than keywords, several in Spanish and Korean, and a recurring shape was some version of "which tools tell me what to do so we appear in AI answer engines". Prompt-shaped demand is already showing up in ordinary Search Console data. You can read your buyers' prompts today without buying anything, which is where peppereffect starts every engagement.
Source: Google Search Console, sc-domain:peppereffect.com, page-level query report, 2 July to 30 September 2026.
Engine-by-engine notes
Perplexity
Perplexity is the engine where classic SEO pays most directly, at 28.6% overlap with Google's top 10, so it's the first place your existing rankings should show up. Its 3.3% overlap with Bing says the reverse is not true. If you're working a page toward Perplexity, the shortest route runs through Google ranking for the same query.
ChatGPT
ChatGPT has the lowest overlap in the set, 8.0% in-text and 6.1% in its reference list, and it's near-identical against Bing at 8.1%. Ranking buys you very little here. What's left, in our practice, is the work that makes a page quotable on its own terms: a direct answer near the top, a claim that is yours rather than a restatement, and third-party corroboration off your own domain. Our guide to getting cited by ChatGPT takes that apart check by check.
Google AI Overviews
Treat AI Overviews as a weakening derivative of ranking rather than a free consequence of it: 76.1% of citations came from top-10 pages in July 2025 and 37.9% in March 2026. Rank still helps more here than anywhere else. It no longer decides the outcome, and the growing share of cited pages from outside the top 100 says the candidate pool now includes pages classic ranking never surfaced.
Gemini and Copilot
Both lean toward Bing, at 14.0% and 16.6% overlap against 8.6% and 8.2% on Google. Neither usually gets its own budget line. If your buyers work inside a Microsoft estate, Copilot may be the engine that matters most and the one you're least likely to be watching.
Frequently Asked Questions
How do I optimize my website for ChatGPT and Perplexity?
Run the same buyer-intent prompt set on both engines, record which pages each one cites, and treat the two result sets as separate work queues. Perplexity's citations overlap Google's top 10 by 28.6%, so ranking work moves it. ChatGPT's overlap is 6.1% to 8.0%, so ranking work barely moves it, and the lever there is a page carrying a direct answer and a claim of your own that other sites corroborate.
Does FAQ schema help you get cited in AI search?
Not as a citation lever. Google's documentation on AI features states: "There's also no special schema.org structured data that you need to add." Accurate schema matched to your visible text is still worth having for rich results and clarity, but the widely repeated multipliers attaching FAQ markup to AI citation rates do not trace to a stated method, and they contradict the platform's own guidance.
What is the difference between AEO, GEO and AI search optimization?
They describe the same goal with different emphasis. Answer engine optimization aims at being cited inside a direct answer, generative engine optimization at being named and recommended by generative engines, and AI search optimization is the umbrella term. The distinction that changes your work is not between the acronyms but between the engines, which we unpack in AEO vs GEO vs LLM SEO.
How do I measure whether AI engines cite my business?
Run a fixed set of at least ten buyer-intent prompts across four or more engines, capture the cited URLs rather than mention counts, and include a positive control in every run. The control is the part usually missing. When we tested our own citation check, a heavily cited domain scored identically to a barely cited one, which means the instrument had no discriminative power and every reading from it was worthless.
Is AI search traffic worth optimizing for when the volume is small?
The volume is small and the intent is not. Orbit Media's study of 97 B2B and lead-generation sites over 28.9 million sessions found AI sources converted at 1.91% on high-intent actions against 0.5% for organic search, while accounting for about 0.5% of visits. Small channel, high intent. We take the volume objection apart in AI is only 2% of my traffic.
Which AI search optimization tool should I start with?
Start with a free grader to confirm the gap exists, then pay for a tracker only once you know which engines your buyers use. Check the engine list before the feature list. A $29 entry plan that omits Gemini leaves you blind on one of the two engines whose citation behaviour diverges most from Google, and no tracker of any price makes you citable on its own.
Measure the right engines before you write another page
We run the prompt set across every engine your buyers use, with controls, and hand you the list of prompts you lose and the pages that should have won them.
Resources
- Ahrefs: Only 12% of AI-cited URLs rank in Google's top 10, 15,000 long-tail queries, July 2025
- Ahrefs: AI Overview citations and top-10 rankings, 863,000 SERPs and 4 million URLs, 2 March 2026
- Ahrefs: Do search rankings drive AI citations?, 1.9 million citations, 21 July 2025
- Google Search Central: AI features and your website
- Pew Research Center: Google users click less when an AI summary appears, 900 adults, 68,879 searches
- Orbit Media: AI traffic conversion rates, 97 B2B sites, 28.9 million sessions
- peppereffect: The Engine Coverage Gap Test, the 12-check diagnostic from this article
- peppereffect: Answer engine optimization, the hub guide
- peppereffect: The AI visibility audit
- peppereffect: The 90-day AI search operating plan
- peppereffect: How LLMs decide what to cite
- peppereffect: Share of model