
AI workflow automation is the use of machine learning, language models and autonomous agents to run a business process from trigger to outcome, including the steps that need judgement rather than a rule. It differs from rule-based automation in one way that decides everything else: the system chooses. And a choice can be wrong while the run that produced it reports success.
Most coverage of ai process automation argues about which platform to buy. That question is close to settled for mid-market B2B, and we have written it up separately in our breakdown of AI automation tools and what they cost. The question nobody answers is the one that costs money after the build: how do you find out that an automation stopped producing correct work, when every dashboard you own says it is fine?
Sources: TheAgentCompany, arXiv 2412.14161, CRMArena-Pro, arXiv 2505.18878, Gartner, 25 June 2025, peppereffect production log.
What this piece covers:
- Where the boundary sits between ai workflow automation, ai process automation and agentic automation
- What independent benchmarks say about the gap between executing a step and finishing a job
- Six incidents from our own estate where the run was green and the output was wrong, with dates and counts
- The Silent-Failure Audit, twelve checks you can run against one workflow this afternoon
- What to measure instead of run status, and how to sequence a build so the checks exist before the volume does
Key Takeaway
Automation platforms measure whether steps executed. Almost none of them measure whether the output was correct, complete, or accepted by the system it was sent to. That is the whole of the reliability problem in ai workflow automation, and it is an instrumentation problem before it is a model problem.
What is AI workflow automation?
AI workflow automation applies machine learning, natural language processing and autonomous agents to a defined business process so it runs without a person in every loop. Rule-based automation handles structured work with fixed branches. AI workflow automation takes the steps where the input varies, the document is unstructured, or the next action depends on context that was not enumerated when the workflow was built.
The practical difference shows up at the exception. A rule-based chain has a finite set of paths, and anything outside them stops the run, loudly. An AI-driven step has no such edge. Hand it a malformed record and it produces something: a plausible summary of nothing, a confident classification of an empty field, a next action derived from a value that was never there. The run completes. The log is clean. Nothing in the platform separates a good answer from a fluent one.
This is why peppereffect treats ai automation workflow design as an instrumentation problem first. The build is rarely the hard part. Zapier, Make and n8n will all carry a well-specified process, and the cost of running one is knowable in advance. What separates an automation you can leave alone from one that quietly loses you customers is whether it can tell you it has gone wrong.
What is AI process automation, and is it the same thing?
AI process automation and AI workflow automation are used interchangeably in most vendor material. The useful distinction is scope. A workflow is one chain from trigger to outcome. A process is the business objective that several workflows serve, plus the handoffs between them, the exception paths and the people still sitting in the middle. Automating a workflow is an engineering job. Automating a process means deciding what happens when the workflow is wrong.
The distinction matters because the failure modes differ, and so does what you need to measure. Below is the version we use with clients before any tool is chosen.
| Scope | What it covers | How it typically fails | What you have to measure |
| Task automation | One step, fixed inputs, deterministic rules | Loudly. The step errors and the run stops | Run status is genuinely sufficient |
| AI workflow automation | One chain end to end, with judgement steps inside it | Quietly. Output is produced but wrong, empty or partial | Output counts, field fill rates, destination read-backs |
| AI process automation | Several chains plus handoffs, exceptions and human review | At the seams. Work falls between two green workflows | End-to-end record tracing, queue age, unprocessed remainder |
| Agentic automation | A goal rather than a path, with tool use and multi-step planning | Plausibly. The agent finishes and reports a result it invented | Independent verification of the result, not the agent's own account |
Framework: peppereffect, from client deployments 2025 to 2026. Related reading: agentic AI against traditional automation and workflow orchestration.
Watch what happens as you move down that table. Run status stops being evidence at row two and is actively misleading by row four. Most teams keep reading it anyway, because it is the only signal the platform hands them for free.
Why do AI workflows fail after they go live?
They fail because the part of the job that platforms measure is the part that already works. Independent benchmarks show agents handling mechanical execution reasonably well and collapsing on the work around it: gathering what they need, holding context across turns, and knowing when they do not have enough to proceed.
Salesforce's CRMArena-Pro benchmark (arXiv 2505.18878, 24 May 2025) makes the split unusually clean. Across nineteen expert-validated sales, service and quoting tasks, leading agents managed over 83 percent on workflow execution when the request arrived complete in a single turn. Give the same agents the full task set and single-turn success falls to roughly 58 percent. Put the request into a multi-turn conversation where the agent has to elicit what it needs, and it drops to about 35 percent. The paper also reports near-zero inherent confidentiality awareness, which targeted prompting improves at some cost to task success.
Carnegie Mellon's TheAgentCompany (arXiv 2412.14161, version 3 dated 10 September 2025) puts 175 realistic tasks inside a simulated software company. The strongest model tested, Gemini 2.5 Pro, completed 30.3 percent of them autonomously and scored 39.3 percent once partial credit is allowed. The category breakdown is the part worth keeping: software engineering tasks score highest, while data science, administrative and finance tasks sit at the bottom, with several models completing none at all. Those bottom categories are where our own client projects start, because that is where the manual hours sit.
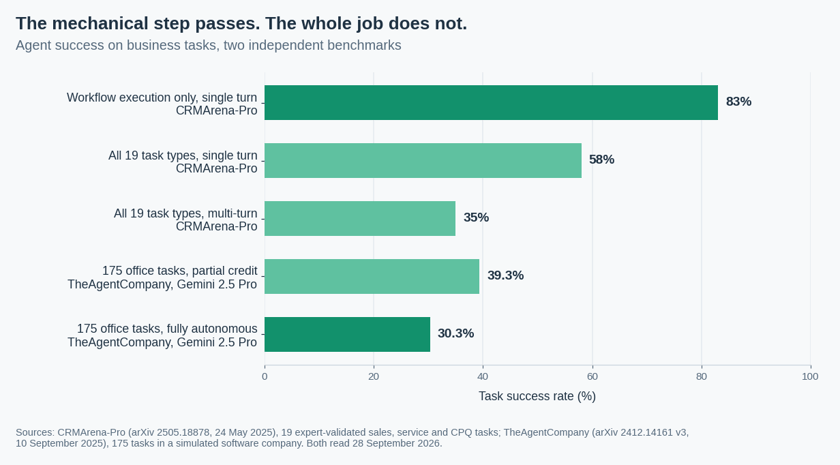
Sources: CRMArena-Pro, arXiv 2505.18878; TheAgentCompany, arXiv 2412.14161 v3. Both read 28 September 2026.
The market data points the same way without explaining the mechanism. Gartner predicted on 25 June 2025 that over 40 percent of agentic AI projects will be cancelled by the end of 2027, citing escalating costs, unclear business value and inadequate risk controls. The same release estimates that only around 130 of the thousands of vendors claiming agentic capability are real.
The figure everyone quotes is the 95 percent from MIT NANDA's The GenAI Divide: State of AI in Business 2025, which reports that 95 percent of organisations are getting zero return on 30 to 40 billion dollars of enterprise investment. Two caveats belong next to it every time. The evidence base is 52 structured interviews, 153 survey responses collected at four industry conferences and a review of 300-plus publicly disclosed initiatives, gathered between January and June 2025. And we could not find a copy hosted by MIT itself, so what circulates are third-party mirrors; the one linked here is what we read on 28 September 2026. Treat it as a well-argued industry report rather than peer-reviewed research. Its diagnosis outlasts its headline number: the systems stay static while the process around them moves.
Key Takeaway
Across two independent benchmarks, agents score highest on the mechanical step and worst on the surrounding work. Your platform monitors the mechanical step. That is why the failures you hear about arrive from a customer rather than an alert.
Six times our own automations reported success and produced wrong data
We run the same class of system we sell, which means our own production log is the most useful dataset we have on this. Over August and September 2026, six incidents in the peppereffect estate shared one property: the platform recorded the run as successful, and the output was wrong. None of them produced an error. All of them cost either money or a week.
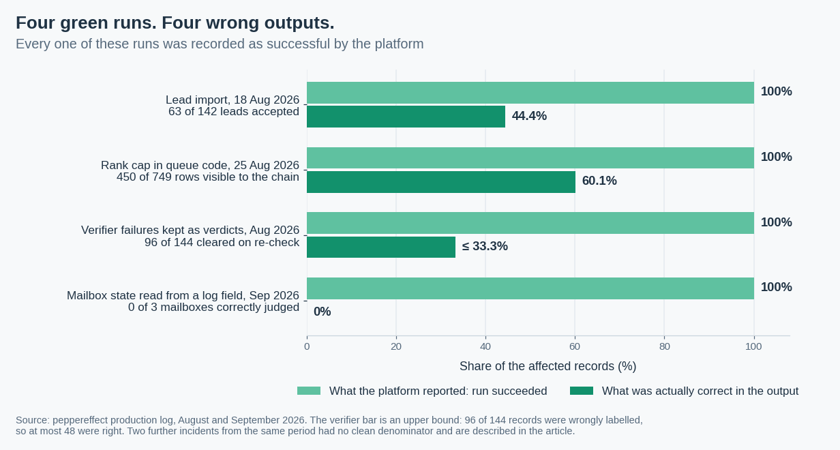
Source: peppereffect production log, August and September 2026. The verifier bar is an upper bound: we know 96 of the 144 records were wrongly labelled, so at most 48 were right. Two of the six incidents had no clean denominator and are described in the table rather than charted.
| What happened | What the run reported | What was actually true | The check that catches it |
| Lead import, 18 August 2026 | 142 records sent, run successful | 63 accepted. 79 rejected silently because an earlier campaign had touched them, and they were the top of the list | Read back what the destination holds and reconcile it against what you sent |
| Rank cap in queue code, 25 August 2026 | Every run green, queue never cleared | A limit of 450 in the code against a table of 749 rows. Everything from row 451 did not exist as far as the chain was concerned | List every cap in code and date-stamp it against current table size |
| Verifier failures kept as verdicts, August 2026 | 144 records marked and skipped on repeat | The verification step had errored. Re-running it cleared 96 of the 144 as fine. We nearly discarded 96 live records under the label of diligence | Store a failed measurement as "not measured", never in the field that holds the business judgement |
| Mailbox state read from a log field, September 2026 | Three accounts reported as permanently failed | All three were sending daily at full inbox placement. The field held the last error ever recorded, not the current state. We made this mistake three times | Confirm for every status field whether it is a state or a historical log |
| Case-sensitive field mapping, 24 September 2026 | Every run successful, every record written | The mapping step read one casing while the upstream service emitted another. Names and company sizes came out empty. 82 records needed repair through a paid API | Validate incoming payloads against an explicit schema and fail on an unknown key |
| Swallowed HTTP error, 14 September 2026 | Clean run, no error surfaced | A continue-on-error setting suppressed an abort, so 97 records stayed in a failed state and were re-pulled on every subsequent run | Route every error branch somewhere that alerts or quarantines |
Source: peppereffect production incident log, entries dated 18 and 25 August, 14, 16 and 24 September 2026.
Two patterns generalise. Five of the six were failures of reading rather than writing: two fields misread, a cap unread, an error unread, a rejection unread. Only one was a failure of writing, and it is the one that nearly destroyed live records. And the mailbox incident happened three times, which is the more useful finding. Knowing the rule is not the same as having a check that enforces it, and the gap between those two is where an automation estate rots.
The mistake that costs the most
Treating a successful run as evidence of correct output. In all six incidents above the run status was accurate: the steps did execute. It was simply answering a different question from the one we needed answered, and we did not notice we were reading the wrong number.
The Silent-Failure Audit: twelve checks for one workflow
Run this against a single workflow, not your whole estate, and answer for the workflow as it runs today rather than as you intend to build it. Tick only what you could show someone. The twelve checks come from the six incidents above and from the benchmark failure modes, in four layers. There is an interactive scored version of the Silent-Failure Audit that keeps everything in your browser and sends nothing anywhere.
| Layer | Check | Pass threshold |
| 1. Does the run tell the truth? | Error route attached to every unattended workflow, and fired on purpose to confirm the alert lands | Every workflow, tested within 90 days |
| 1 | No step continues past an error without an error branch that alerts or quarantines | Zero unrouted continue-on-error steps |
| 1 | Runtime baseline recorded, and a suspiciously fast run raises an alert | Alert below half the normal runtime |
| 2. Did the output arrive? | Every run asserts a plausible output record count before it writes | A count assertion on every write step |
| 2 | Required fields are measured for fill rate rather than assumed | A fill-rate check on every required field |
| 2 | What the destination accepted is read back and reconciled against what was sent | A read-back on every external write |
| 3. Is the output correct? | Every status field you act on has been confirmed as a current state, not a historical log | Documented for every status field in use |
| 3 | Incoming field names validated against an explicit schema, with unknown or missing keys failing the run | Schema validation at every ingest boundary |
| 3 | A person reads finished records end to end before a batch touches the outside world | 15 or more whole records since the last change |
| 4. Can you still see the whole set? | Every limit, page size and cap in code is listed and compared with current volume | No cap sitting below current volume |
| 4 | New work is processed before retries, so a poisoned retry set cannot starve the queue | New-before-retry ordering confirmed in the query |
| 4 | A failed check is stored as "not measured" and re-queued, never written as a verdict | No failure state doubling as a business judgement |
The Silent-Failure Audit, peppereffect, 28 September 2026. Derived from our own incident log and from the benchmark failure modes above.
Scoring is blunt on purpose. Eleven or twelve and the workflow can be left alone, because you would hear about a failure from your own system before a customer did. Eight to ten and it runs unattended while failing in private, which is the expensive shape. Four to seven and a green run currently tells you almost nothing. Below four, it should not run without someone watching it.
Check nine is the one teams argue about, so here is the evidence. When we first read finished records end to end before a send, eleven of eighteen were broken, in a batch two hours from going out. A 61 percent defect rate, in a chain whose gates were reporting clean; three of the five turned out to be leaking. Reading whole records catches what no field-level assertion will, because the defects live in the relationship between fields rather than in any one of them.
Running an automation estate you can no longer see into? We install the instrumentation layer alongside the workflows.
What should you monitor instead of run status?
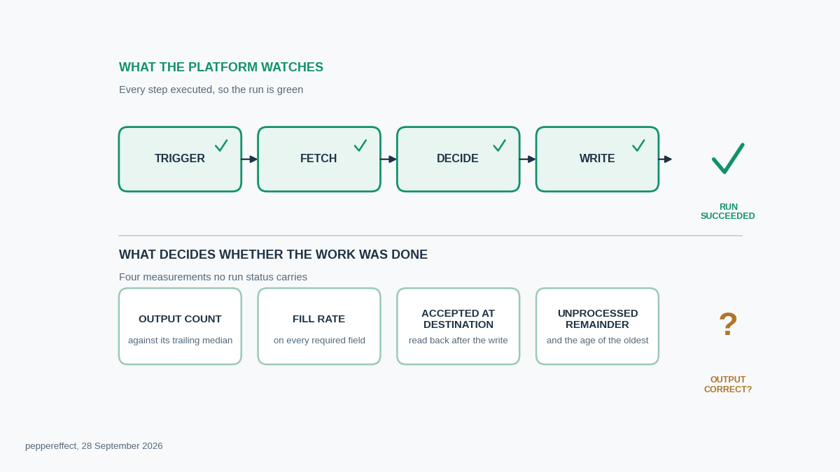
Monitor the output, not the execution. Run status answers whether the steps ran. The four signals below answer whether the work was done, and each can be computed inside the workflow itself with no extra tooling. Put them in before volume arrives, because every one needs a baseline and a baseline takes time to earn.
Output volume against its own history
Record count per run, compared with the trailing median rather than a fixed number. Zero rows is the case this catches most often, and a chain producing zero rows usually reports a faster run than normal, so the two signals confirm each other.
Fill rate on every field a later step depends on
The share of output records where the field carries a value. An empty string is not an error to any platform we have used, which is why it needs measuring rather than trusting. Our case-sensitive mapping incident would have surfaced on the first run.
Acceptance at the destination
What the receiving system holds after the write, read back and compared with what was sent. Every upload interface reports what left your side. Almost none report what the other side kept, and that difference is where 79 of our 142 records went.
Unprocessed remainder
How many records are eligible and have not been through, plus the age of the oldest. This is the only signal that catches a hidden cap, because a capped chain looks healthy from the inside. It is also how you spot a queue starving itself on retries.
Method: peppereffect. Related: metrics for agentic systems and how we run a workflow audit.
On the platform side, treat error routing as something you attach rather than something you receive. n8n documents the error workflow as a per-workflow setting that runs when an execution fails, so a workflow without one records the failure in its execution list and tells nobody. The behaviour is reasonable. The default is what catches people, one workflow at a time, as the estate grows past the point where anyone remembers which ones were set up properly. The limits worth knowing before you commit to n8n covers the rest.
How do you build AI process automation you can leave running?
Build the check before the step it checks, and expand only once the current layer is instrumented. Each phase below adds capability after the previous one can report on itself. It takes longer to reach the impressive demo and far less time to reach something that survives a quarter.
- Mark where judgement enters. Find every point where a human currently decides something a rule cannot express. Those marks are your future failure sites and the only places worth applying AI. Everything else is ordinary automation.
- Build the deterministic spine and instrument it. Rule-based path first, with output counts, fill rates and destination read-backs from day one. This phase is boring, which is why it gets skipped, and skipping it drops the judgement steps onto a chain with no baseline.
- Add judgement steps one at a time, each with its own check. A classification step needs verification against a signal the model did not see. An extraction step needs a fill-rate floor. If you cannot state what would prove the step wrong, it is not ready for production. Route low confidence and irreversible actions to a real review queue with a real owner, which is what human-in-the-loop design means in practice.
- Only then hand a goal to an agent. Multi-step planning across tools has the widest gap between demo and production, and the benchmarks above are the reason. When you get there, the handoff between agents deserves more design attention than the agents themselves.
The ordering is about baselines rather than risk appetite. A check comparing this run against the trailing median needs a history to compare against, and you cannot retrofit that history onto a workflow you have already scaled. Governance belongs inside the same sequence: an audit trail recording what a workflow decided, on what input, beats a policy document about responsible AI, and it is the artefact you will want when something has been quietly wrong for six weeks. We have written up what a workable B2B AI governance framework contains and the pattern behind most failed AI projects, which is rarely the model.
Frequently Asked Questions
What is AI workflow automation?
AI workflow automation is the use of machine learning, natural language processing and autonomous agents to run a business process from trigger to outcome, including steps that require judgement rather than a fixed rule. It differs from rule-based automation because the system decides rather than follows a branch, which means it can produce a wrong result without producing an error.
What is the difference between AI process automation and AI workflow automation?
The terms are used interchangeably, but the useful distinction is scope. A workflow is one chain from trigger to outcome. A process is the business objective that several workflows serve, including the handoffs between them and the people still in the middle. Workflow failures are usually silent and internal. Process failures happen at the seams, where work falls between two workflows that are both reporting success.
How is AI workflow automation different from RPA?
Robotic process automation follows fixed scripts against structured inputs and stops when reality departs from the script. That stopping is a feature, because it is loud. AI workflow automation handles unstructured input and contextual decisions, so it has no equivalent stopping point: hand it a malformed record and it returns a confident answer derived from nothing. RPA fails visibly. AI-driven process automation fails quietly, which is why it needs output-level instrumentation that RPA never did.
How reliable are AI agents in real business workflows?
Less reliable than the demos suggest, and the gap is specific rather than general. In Salesforce's CRMArena-Pro benchmark, agents scored over 83 percent on single-turn workflow execution, roughly 58 percent across the full task set in a single turn, and about 35 percent once those tasks ran as multi-turn conversations. In Carnegie Mellon's TheAgentCompany benchmark of 175 office tasks, the best model completed 30.3 percent autonomously, with administrative and finance tasks lowest. Mechanical execution is solid. Everything around it is not.
How do you tell whether an AI automation is silently broken?
Stop reading run status and start reading output. peppereffect measures four signals inside every production workflow: output record count against its trailing median, fill rate on every field a later step depends on, what the destination accepted after the write, and how many eligible records have still not been processed. Each catches failures a green run conceals, and the fourth is the only one that catches a hidden cap.
How much does AI workflow automation cost to run?
Platform cost depends far less on the headline subscription price than on how each vendor counts a billable unit, which is why identical workflows can differ by an order of magnitude in monthly cost at a comparable entry price. We break that down with current vendor pricing in what AI automation actually costs. Budget separately for the instrumentation layer, which is usually the cheaper half and always the first thing cut.
Install automation you can stop watching
peppereffect architects AI operating systems for B2B companies, with the output-level instrumentation built in rather than bolted on afterwards. We start by auditing what your current workflows can and cannot tell you.
Resources
- CRMArena-Pro, a benchmark of LLM agents across business scenarios and interactions (arXiv 2505.18878, 24 May 2025)
- TheAgentCompany: Benchmarking LLM Agents on Consequential Real World Tasks (arXiv 2412.14161, version 3, 10 September 2025)
- Gartner: Over 40% of Agentic AI Projects Will Be Canceled by End of 2027 (25 June 2025)
- MIT NANDA: The GenAI Divide, State of AI in Business 2025 (third-party mirror, not peer reviewed)
- n8n documentation: handle errors gracefully
- The Silent-Failure Audit, interactive version (peppereffect, 28 September 2026)
- AI automation tools for B2B: real costs and failure modes